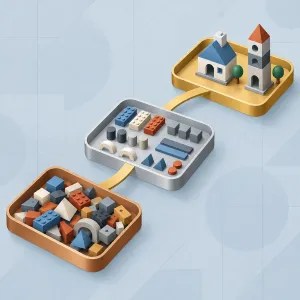
Medallion architecture is the go-to for handling analytical data, particularly with the prominence of lakehouses in Databricks and Fabric.
Whilst the layers are well defined, their definitions don’t tell you where particular tasks belong. So here I wanted to present my view from a more practical perspective of what goes into each layer.
Layering
Let’s start by recapping the layers:
- 🥉 Bronze: landing area for data in its full, raw, and unaltered format
- 🥈 Silver: where transformations take place including data cleansing, quality checks, and standardisation
- 🥇 Gold: addition of calculations and presentation of data ready for consumption
It’s simple and clear. But the reality of implementing these can vary wildly, so let’s work through each layer to dig into what goes where.
🥉 Landing in bronze
The aim here is to collect all our source data and preserve that in its rawest form for processing.
Collect your data, and retain the history. History not only in terms of incremental data (say, sales), but also modified data (pricing, for example). Tracking modifications over time can provide context to facts, and it’s not always easy to retrospectively identify changes and reverse engineer these.
Bring the data in without transformation. Parquet or flat files are great. For APIs you can store the output directly, say JSON. If it’s in another data store, the goal is to copy whilst preserving as much – and inferring as little – as possible.
There can be slight wrinkles with odd sources. For example, compressed data could be extracted as part of the ingestion to allow it to be used directly as we move into the Silver layer.
Goal: collate and retain source data in its rawest form
🥈 Transformations in silver
Silver is where data is tidied and standardised into a consolidated view of your data.
This is where transformations primarily live. We take the data from the Bronze layer and bring it into a common model. Typically I prefer normalised to provide clear entities and remove duplication. These transformations would include:
- Data type conversion and applying default values
- Handling of duplicate or invalid records
- Joins, lookups, or unions
Even though Silver is a single layer, these transformations will likely be applied across multiple stages. For example, an initial stage may handle default values, and a further stage may union multiple sources and provide a consolidated view. Cleansing is iterative.
The standardisation from this layer is the foundation of what we’ll create in the Gold layer. This refined data also lends itself well to data science and analysis without the need for a Gold presentation layer.
Goal: cleanse and structure data into common entities
🥇 Presentation in gold
The Gold layer is where we model the data for consumption. The home stretch.
This is the layer where we produce a schema which answers questions and can be consumed, typically via a semantic model. I see the key operations in this layer include:
- Dimensional modelling to translate the Silver layer into facts and dimensions
- Define business calculations, metrics, and KPIs
- Create aggregate datasets for common use cases
Here I think about reducing the data from Silver down to fit the outputs required, and then growing this by adding calculations based on business rules or required metrics.
As with the Silver layer, you can create multiple stages within the Gold layer. An early stage can provide common metrics – for example revenue is relevant both operationally and financially – but its definition should only exist in one place.
Another example would be a stage that serves a department but you want a subset of that – which inherits the same metric definitions – to feed an LLM supporting executive decisions. Some would argue this distinction forms a ‘platinum’ layer. If a specific boundary is needed above the Gold layer I could understand the reasoning, although I haven’t personally been in a position needing this.
Goal: shape data to provide datasets to solve specific problems, including common metrics and aggregations
Wrap up
Medallion architecture is a core engineering framework, but layers sometimes blur when it comes to implementation. Here I wanted to lay out a more practical guide on the distinction of what goes where when I model.
- 🥉 Bronze: preserve data as close to source as possible, including changes over time
- 🥈 Silver: transform into a coherent model that can be reused
- 🥇 Gold: define metrics and tailor data based on consumption needs
Knowing why each layer in the medallion architecture exists is foundational, but understanding what resides in them ensures each has their distinct responsibilities without the blurring of boundaries.
Personally I feel more focus should be spent designing a Silver layer which appropriately represents an entire suite of data. Whilst not as visible itself, it underpins the ability to deliver consistent and high quality Gold layers. Silver is where solid engineering really shines.

